TRex: Practical Type Reconstruction for Binary Code
Jay Bosamiya
34th USENIX Security Symposium (USENIX Security '25) · Day 3 · Software Security 4: Fuzzing and Other Software Analysis
Overview
In the intricate world of reverse engineering, understanding the behavior of compiled binary code is a monumental task, often hampered by the loss of high-level information during the compilation process. This talk introduces TRex, a novel tool designed to significantly alleviate the tedium associated with binary analysis by offering a practical approach to type reconstruction. The speaker, Jay Bosamiya, highlights a fundamental flaw in existing decompiler methodologies: their persistent, often futile, attempt to "recover" the original source code types. TRex challenges this paradigm, proposing that instead of striving for an impossible ground truth, reverse engineers truly desire an accurate representation of a program's observable behavior through its types.
Key moments
- 0:30 Decompiler failures on a simple linked list
- 2:40 Why perfect type recovery is fundamentally impossible
- 3:00 Shifting focus to type reconstruction for observable behavior
- 5:00 Introducing structural types and type rounding in T-Rex
- 7:00 T-Rex correctly reconstructs types for the linked list example
- 8:20 T-Rex outperforms others on a reverse engineering metric
TRex: Practical Type Reconstruction for Binary Code
Speakers: Jay Bosamiya
Conference: USENIX Security
YouTube: https://www.youtube.com/watch?v=5cOyIJt2cAw
Overview
In the intricate world of reverse engineering, understanding the behavior of compiled binary code is a monumental task, often hampered by the loss of high-level information during the compilation process. This talk introduces TRex, a novel tool designed to significantly alleviate the tedium associated with binary analysis by offering a practical approach to type reconstruction. The speaker, Jay Bosamiya, highlights a fundamental flaw in existing decompiler methodologies: their persistent, often futile, attempt to "recover" the original source code types. TRex challenges this paradigm, proposing that instead of striving for an impossible ground truth, reverse engineers truly desire an accurate representation of a program's observable behavior through its types.
The core of TRex's innovation lies in its shift from type recovery to type reconstruction, a distinction that profoundly impacts its design and effectiveness. While decades of research have gone into decompilers, and tools like Ghidra and Hex-Rays are widely used, they frequently produce incorrect or unhelpful type information, particularly for complex structures like linked lists. TRex, through a deductive, constraint-based technique, aims to provide more precise and actionable type information, ultimately enhancing a reverse engineer's ability to comprehend complex software, especially in scenarios where source code is unavailable or proprietary.
The significance of this work extends beyond academic novelty. By providing a reliable and deterministic method for inferring robust type information from binaries, TRex addresses a critical pain point for practitioners in security analysis, vulnerability research, and malware analysis. Its structural type-based approach offers a more accurate reflection of how data is manipulated within a program, which is often more valuable than a speculative guess at the original source-level types. This talk not only presents a new tool but also redefines a core problem in binary analysis, paving the way for more effective and less frustrating reverse engineering workflows.
Background
▶ Watch: Decompiler failures on a simple linked list (0:30)
The landscape of software development is vast, encompassing legacy systems built over decades, often lacking accessible source code, and frequently plagued by security vulnerabilities. Decompilers are indispensable tools in this environment, acting as bridges between low-level machine code and human-readable representations. However, despite extensive academic and engineering efforts spanning decades, the practical output of decompilers often falls short, necessitating significant manual effort from reverse engineers to interpret and correct their generated types.
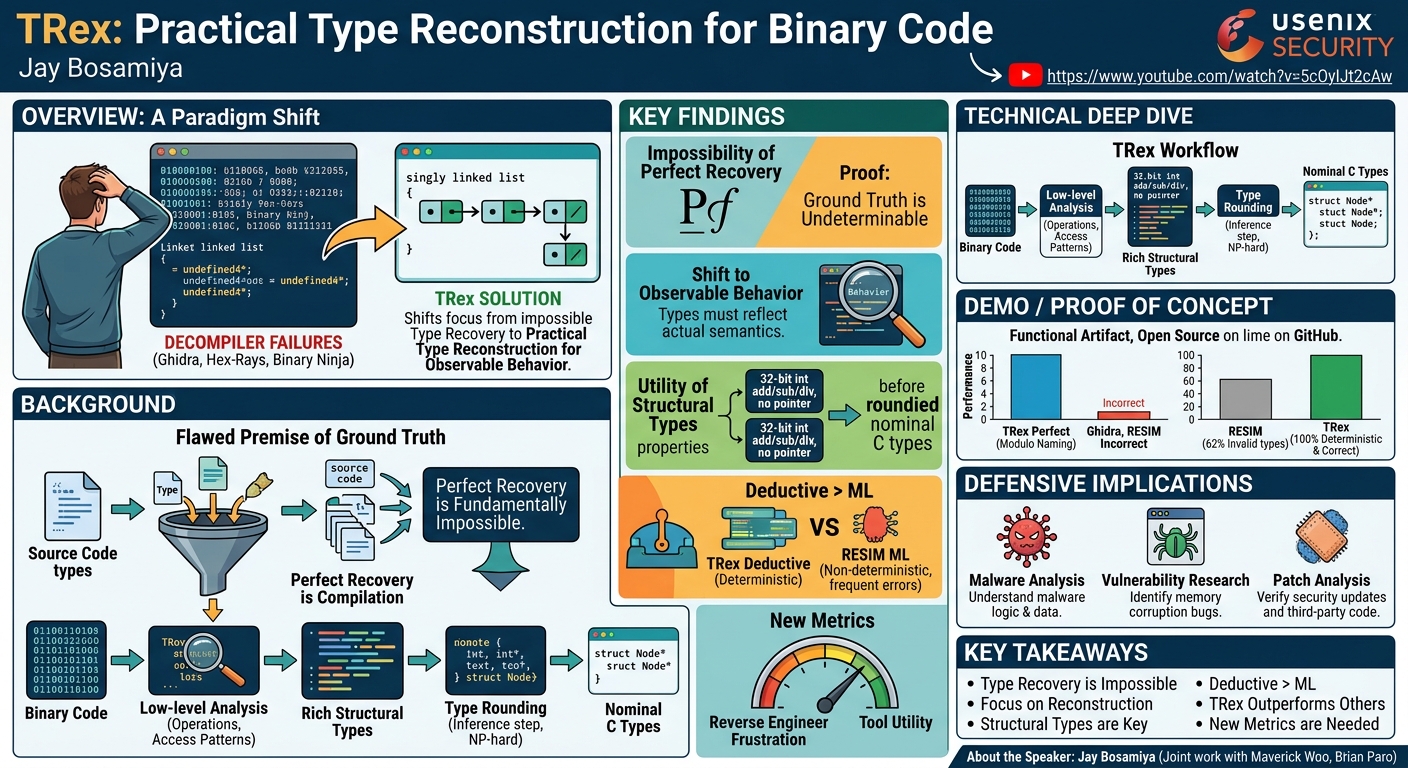
A prime example of this inadequacy is demonstrated with a simple singly linked list. When such a structure is compiled into machine code, much of its high-level type information, crucial for understanding its organization and manipulation, is lost. Passing this binary to a decompiler like Ghidra, developed by the NSA, yields mixed results. While primitive types like int might be correctly identified in terms of size (e.g., undefined4), complex pointer types, such as node*, are often completely misrepresented, appearing as an undefined4* – a clearly incorrect and unhelpful interpretation. The situation can be even worse with other popular commercial tools like Hex-Rays (part of IDA Pro) or Binary Ninja, which, in some cases, might incorrectly infer an int as an 8-byte int64 and fail to accurately represent the linked list structure altogether.
This pervasive issue led the researchers to question the underlying assumptions of prior academic work. Previous endeavors in automated type inference, broadly categorized as type recovery (deductive techniques) and type prediction (machine learning-based techniques), shared a common goal: to recover the "ground truth" of the original source code types. This approach, while intuitively appealing, rests on an implicit assumption that a perfect recovery tool could, in theory, reconstruct the exact source code types, modulo naming conventions. However, the speaker argues that this assumption is fundamentally flawed. Through detailed analysis, the paper associated with this talk provides proof that a singular "ground truth" is often impossible to ascertain, making perfect type recovery an unachievable goal. This inherent impossibility necessitates a paradigm shift, moving the focus from a futile attempt at recovery to a more pragmatic and achievable goal: type reconstruction. The problem isn't just about imperfect tools; it's about a flawed foundational premise in the field.
Key Findings
▶ Watch: Shifting focus to type reconstruction for observable behavior (3:00)
The research presented in this talk reveals several pivotal findings that challenge conventional wisdom in binary type analysis and lay the groundwork for a more effective approach:
- Impossibility of Perfect Type Recovery: A core discovery is the mathematical proof that perfect type recovery, aiming to reconstruct the original source code types, is fundamentally impossible. The assumption of a singular "ground truth" for types in compiled binaries is flawed because compilation inherently loses information, and multiple source type configurations can lead to identical binary representations. This insight necessitates a re-evaluation of the goals of automated type inference.
- Shift from Recovery to Reconstruction: Given the impossibility of perfect recovery, the talk advocates for a paradigm shift towards type reconstruction. Instead of chasing an elusive ground truth, the objective should be to generate types that accurately capture the observable behavior of the program. Reverse engineers, it is argued, primarily seek to understand program semantics, and types that precisely reflect these semantics, even if not identical to the original source types, are more valuable.
- Utility of Structural Types: The research highlights the critical importance of employing structural types throughout the type analysis process, delaying the conversion to nominal (C-like) types until the final stages. Unlike nominal types, which are language-specific and can lead to complex and imprecise mechanisms when applied to binary analysis, structural types focus on the properties and operations supported by data. This allows for a more precise and natural representation of program behavior, even for constructs not directly expressible in C, before being "rounded" into C-like equivalents for human readability.
- Value of Deductive Techniques in an ML-Dominated World: Despite the increasing prevalence of machine learning in various fields, including binary analysis, this work demonstrates the enduring and high value of deductive, constraint-based techniques, especially when correctness and determinism are paramount. While ML-based approaches like RESIM can achieve high accuracy in some metrics, they often suffer from non-deterministic results and frequently produce invalid or functionally incorrect types, making them unreliable for critical reverse engineering tasks. TRex's deterministic, deductive approach offers a robust alternative where precision matters most.
- New Metrics for Evaluation: Recognizing that the traditional "ground truth" metric for evaluating type inference tools is flawed, the research proposes a new, reverse engineering-focused scoring metric. This metric prioritizes avoiding frustration for the reverse engineer by rewarding types that accurately reflect observable behavior and penalizing misleading or incorrect inferences. This new evaluation framework better reflects the practical utility of a type reconstruction tool.
Technical Deep Dive
▶ Watch: Introducing structural types and type rounding in T-Rex (5:00)
TRex's technical foundation is rooted in a deductive constraint-based technique that fundamentally deviates from prior approaches by prioritizing structural types over nominal types throughout the majority of its analysis. This design choice is critical to its success in accurately reconstructing program behavior.
The general workflow of TRex begins with the binary code, from which it extracts low-level information about data access patterns, operations performed on data, and control flow. Instead of immediately attempting to map these observations to C-like types (nominal types), TRex constructs a rich representation using structural types. A structural type is defined not by a name (like int or struct Node) but by the set of operations and properties it supports. For instance, a structural type might specify that a piece of data supports 8-bit or 32-bit copying, 32-bit integer addition, subtraction, and signed division, and does not act as a pointer. This approach allows TRex to capture the precise behavior of data within the program, even for scenarios that might be difficult or impossible to express directly using standard C types.
The contrast with prior work, which often uses nominal types from the outset, is stark. Attempting to force binary-derived information into C-like nominal types too early in the analysis can lead to complex, brittle mechanisms and imprecise results. Structural types, being more abstract and focused on behavior, are considered the "most natural kind" for the task of type reconstruction because they maintain fidelity to the actual machine-level operations. TRex supports outputting a comprehensive range of C-like types, including pointers, structs, unions, arrays, and even complex recursive types like linked lists, demonstrating its ability to handle intricate data structures.
A key innovation in TRex is type rounding. After the initial analysis using structural types, and as late as possible in the process, TRex performs type rounding to convert these precise structural representations into familiar C-like nominal types. Type rounding is essentially an inference step where, based on the observed operations, additional, logically consistent operations are inferred. For example, if a structural type indicates support for addition, subtraction, and division on 32-bit integers, it is highly probable that it also supports multiplication. Type rounding applies such logical inferences, effectively "rounding out" the structural type until it corresponds to a known nominal type. This process helps map the granular behavioral descriptions back to common programming language constructs. The talk mentions that the problem of type rounding is NP-hard, highlighting the computational complexity involved in this inference step.
TRex also addresses the challenge of non-conservative reasoning safely. While the paper provides more details, this likely refers to how the system makes inferences that go beyond strictly observed behavior (e.g., in type rounding) without introducing unsoundness or incorrectness. The system is designed to be deterministic, a significant advantage over machine learning approaches like RESIM, which can produce non-deterministic and often invalid results. TRex's complete determinism means that for the same input, it will always produce the same output, which is crucial for reliability in reverse engineering.
Furthermore, the research details the design of a suitable metric to evaluate these tools despite ground truth being impossible. This reverse engineering-focused scoring metric moves beyond simply comparing output types to original source types. Instead, it prioritizes the practical utility of the generated types for a human reverse engineer, rewarding clarity and correctness of observable behavior and penalizing outputs that would lead to frustration or misinterpretation. This innovative metric acknowledges the real-world goals of reverse engineering, where understanding program behavior often trumps exact source code recovery.
Demo / Proof of Concept
▶ Watch: T-Rex correctly reconstructs types for the linked list example (7:00)
While the talk did not feature a live, interactive demonstration of TRex, the speaker explicitly stated that the tool's artifact is available, functional, and reproducible, with its source code on GitHub. This indicates that TRex is a concrete, working implementation of the proposed type reconstruction methodology, not merely a theoretical concept.
The effectiveness of TRex is showcased through its performance on the aforementioned singly linked list example. Unlike Ghidra, Hex-Rays/IDA Pro, or Binary Ninja, which all produce incorrect or highly problematic type inferences for this common data structure, TRex is able to reconstruct the types "perfectly correct modulo naming". This means it accurately identifies the structure, its pointers, and the types of its members, providing a significantly more useful representation for a reverse engineer.
The talk also provides a quantitative comparison against existing tools, using both traditional and a new reverse engineering-focused metric.
Under the standard metric (where a type is considered correct if its C representation, after normalization, is identical to the source type), TRex outperforms both Ghidra and RESIM. This is notable because even when evaluated against the "recovery" paradigm, TRex's reconstruction approach yields superior results.
The comparison with RESIM, a machine learning-based type prediction tool that won a distinguished paper award, is particularly insightful:
- RESIM produces nondeterministic results.
- It is correct only 2% of the time according to the standard metric.
- 36% of the time, it produces a valid but incorrect C type.
- A staggering 62% of the time, RESIM outputs types for which "there's no possible equivalent valid C type," rendering its results largely unreliable and difficult to depend upon in practice.
In stark contrast, TRex is completely deterministic, ensuring consistent and predictable output. When evaluated with the reverse engineering-focused scoring metric, which prioritizes avoiding frustration for the analyst, TRex continues to outperform both Ghidra and RESIM. Interestingly, under this new metric, Ghidra and RESIM swap positions in relative performance, highlighting the impact of a more practical evaluation criteria. This quantitative and qualitative evidence strongly validates TRex's practical utility and superior performance in generating meaningful type information for binary code analysis.
Defensive Implications
▶ Watch: T-Rex outperforms others on a reverse engineering metric (8:20)
The advancements in binary type reconstruction offered by TRex have significant and direct defensive implications for cybersecurity professionals. By providing more accurate, deterministic, and behaviorally-aligned type information, TRex empowers defenders with enhanced capabilities for understanding and analyzing malicious software, identifying vulnerabilities, and verifying security patches.
Firstly, in malware analysis, understanding the data structures and function signatures used by an adversary is paramount. Malware often employs complex, obfuscated, or custom data types to evade detection and hinder analysis. Traditional decompilers frequently struggle with these, leaving analysts to manually infer types, a time-consuming and error-prone process. TRex's ability to precisely reconstruct types, even for recursive structures and complex compositions, directly translates into a clearer understanding of malware's internal logic, its communication protocols, and the data it manipulates. This can accelerate the identification of command-and-control structures, exploited vulnerabilities, and data exfiltration mechanisms.
Secondly, TRex can significantly aid in vulnerability research and exploit development/analysis. When analyzing a proprietary binary for potential vulnerabilities, accurately understanding the types of arguments passed to functions, the layout of structs, and the sizes of arrays is critical for identifying memory corruption bugs (e.g., buffer overflows, use-after-frees, type confusion). Incorrect type inference by decompilers can obscure these vulnerabilities or lead to misinterpretations. TRex's deterministic and precise output reduces this ambiguity, allowing researchers to more effectively pinpoint potential weak points in software, whether for responsible disclosure or for understanding active exploits in the wild.
Finally, for patch analysis and binary auditing, TRex offers a robust tool to verify the effectiveness of security updates or to audit third-party binaries. When a vendor releases a patch, security teams often need to understand what exactly changed at the binary level and how those changes affect security. By providing clearer type information, TRex can facilitate more accurate binary diffing and analysis, helping defenders confirm that a patch genuinely addresses a reported vulnerability and doesn't introduce new ones. In auditing scenarios, where source code is unavailable, TRex can help establish a more comprehensive understanding of a binary's functionality and potential risks, strengthening an organization's security posture. In essence, by reducing the "tedium" and increasing the accuracy of reverse engineering, TRex directly contributes to a more efficient and effective defensive security strategy.
Key Takeaways
- Type Recovery is Fundamentally Impossible: The assumption of a singular "ground truth" for source code types in binaries is flawed; perfect recovery is an unachievable goal due to information loss during compilation.
- Focus on Type Reconstruction: The goal of binary analysis tools should shift from attempting to "recover" original types to "reconstructing" types that accurately capture the observable behavior and semantics of the program.
- Structural Types are Key: Using structural types throughout the analysis, and delaying conversion to nominal C-like types, provides a more precise and natural way to represent and understand program behavior from binaries.
- Deductive Techniques Remain Valuable: Even in an era dominated by machine learning, deterministic, deductive, and constraint-based approaches like TRex offer high value and superior correctness, especially where reliability and precision are critical.
- TRex Outperforms Existing Tools: TRex demonstrates superior performance over both commercial decompilers (Ghidra, Hex-Rays/IDA Pro, Binary Ninja) and state-of-the-art ML-based solutions (RESIM) in producing accurate and useful type information.
- New Evaluation Metrics are Needed: Traditional metrics based on "ground truth" are insufficient; new reverse engineering-focused metrics that prioritize practical utility and avoid analyst frustration are essential for evaluating type inference tools.
About the Speaker(s)
The talk was presented by Jay Bosamiya. Based on the provided metadata and transcript, no specific title or company affiliation was mentioned during the presentation. The work was described as joint work with Maverick Woo and Brian Paro.
Reviews
Dr. Zero (Offensive Security Researcher) — STRONG ACCEPT
Solid, foundational binary analysis research that earns its place at USENIX Security. The core insight — that perfect type recovery is mathematically impossible and the field has been chasing the wrong goal — is genuinely clarifying, and the structural-types-first approach backed by a deductive constraint engine is the right answer to the right question. The RESIM comparison (62% of outputs aren't valid C types, and it's a distinguished paper) is the kind of result that should make people uncomfortable in a productive way.
Heather Calloway (CISO) — PASS
Technically rigorous work on binary type reconstruction with a legitimate conceptual contribution — the recovery-vs-reconstruction distinction is meaningful, and the RESIM comparison is damning in a useful way. But this is deep binary analysis research with no governance angle, no institutional relevance, and nothing for a CISO, board, or security program to act on.
→ Top-rated talks at 34th USENIX Security Symposium (USENIX Security '25)
All talks from 34th USENIX Security Symposium (USENIX Security '25)