Code is not Natural Language: Unlock the Power of Semantics-Oriented Graph Representation for Binary Code Similarity Detection
Haojie He, Xingwei Lin, Ziang Weng, Ruijie Zhao, Shuitao Gan, Libo Chen, Yuede Ji, Jiashui Wang, Zhi Xue
33rd USENIX Security Symposium · Day 1 · USENIX Security '24 · USENIX Security '24
Overview
Binary code similarity detection is a foundational task in cybersecurity, aiming to determine the semantic equivalence between binary functions. This is particularly challenging when functions originate from the same source code but have been subjected to diverse compilation techniques, optimization algorithms, or different hardware architectures. The ability to accurately identify such semantic similarities is critical for a wide array of security applications, including the discovery of vulnerabilities in closed-source firmware, recovery of binary function symbols, detection of software plagiarism, and identification of license violations.
Key moments
- 0:27 Importance of binary code similarity detection
- 2:07 Overview of existing instruction stream and CFG methods
- 3:57 Fundamental differences: natural vs. assembly language
- 5:58 Examples of NLP limitations with code semantics
- 7:37 Introducing the Semantics-Oriented Graph (SOG) representation
- 8:00 Key principles of SOG: semantic constraints over position
Code is not Natural Language: Unlock the Power of Semantics-Oriented Graph Representation for Binary Code Similarity Detection
Speakers: Haojie He; Xingwei Lin; Ziang Weng; Ruijie Zhao; Shuitao Gan; Libo Chen; Yuede Ji; Jiashui Wang; Zhi Xue
Conference: USENIX Security '24
YouTube: https://www.youtube.com/watch?v=DiKXADHt2vc
Overview
Binary code similarity detection is a foundational task in cybersecurity, aiming to determine the semantic equivalence between binary functions. This is particularly challenging when functions originate from the same source code but have been subjected to diverse compilation techniques, optimization algorithms, or different hardware architectures. The ability to accurately identify such semantic similarities is critical for a wide array of security applications, including the discovery of vulnerabilities in closed-source firmware, recovery of binary function symbols, detection of software plagiarism, and identification of license violations.
Presented by a colleague on behalf of first author Haojie He, this talk introduces a paradigm shift in binary code similarity detection, challenging the prevalent assumption that binary code can be effectively treated as natural language. The research, a collaborative effort between Shanghai Jiao Tong University, ANT Group, and the University of Texas at Arlington, argues that this natural language processing (NLP)-centric approach overlooks crucial code-specific properties and semantic structures inherent in assembly languages.
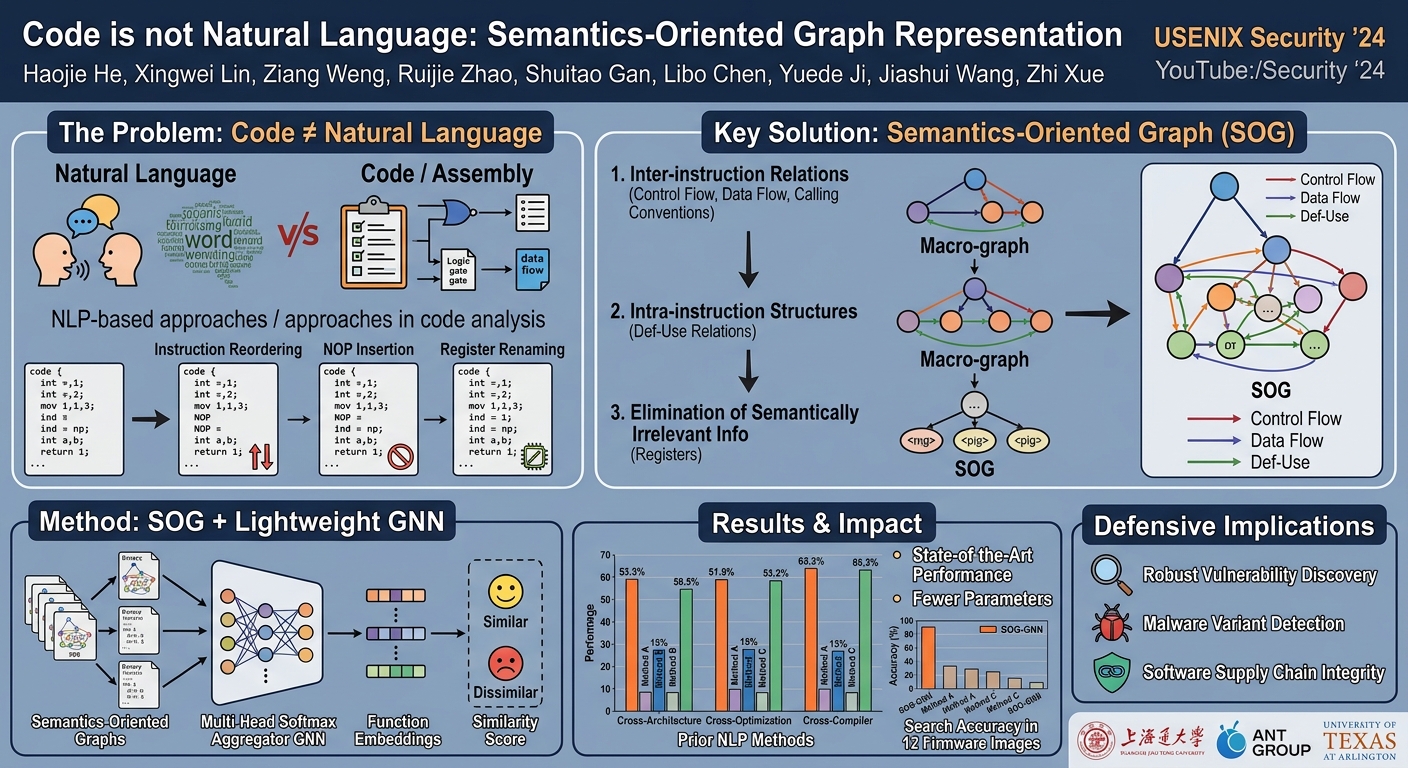
The core contribution of this work is the development of a novel Semantics-Oriented Graph (SOG) representation for binary code. This SOG explicitly captures the well-defined semantic structures of binary functions while intentionally discarding semantically irrelevant information, such as instruction order or specific register choices. Coupled with a lightweight multi-head softmax aggregator based Graph Neural Network (GNN), the proposed method demonstrates significant performance improvements over existing techniques across various challenging scenarios, including cross-architecture and cross-optimization level comparisons, all while utilizing substantially fewer model parameters. This advancement promises more accurate, efficient, and generalizable solutions for critical binary analysis tasks.
Background
▶ Watch: Importance of binary code similarity detection (0:27)
The landscape of binary code similarity detection has traditionally been dominated by a common framework: binary functions are first transformed into numerical vectors, or embeddings, through a learnable method, typically leveraging neural networks. The semantic similarity between functions is then approximated by the similarity scores of their respective vectors. The efficacy of this approach hinges entirely on the embedding method's ability to map semantically similar binary functions to similar vector representations.
Existing research in this domain generally falls into two broad categories: instruction stream based and Control Flow Graph (CFG) based methods. Instruction stream based approaches treat binary functions as linear sequences of tokens, akin to natural language sentences, and apply established Natural Language Processing (NLP) techniques. These methods often abstract instructions into a stream of symbols and attempt to learn patterns from their sequential arrangement. In contrast, CFG based approaches typically consider basic blocks as the fundamental units, treating them as "natural language sentences" and aggregating their features using Graph Neural Networks (GNNs) that operate on the control flow structure of the function.
However, a central tenet of this research is a critical re-evaluation of the assumption that "code is natural language." The speakers highlight that while NLP-based methods might be convenient and intuitive, they fundamentally ignore many unique properties of code. Empirical evidence and prior work indicate that CFG-based methods generally outperform instruction stream based methods, particularly in challenging scenarios like cross-architecture detection, where instruction stream methods often prove incapable or significantly less effective.
The fundamental divergence, the authors argue, stems from the very purpose of these languages. Assembly languages are meticulously designed for precise machine execution, necessitating well-defined structures, semantics, and conventions. This allows for accurate and relatively easy parsing of syntactic and semantic dependencies between tokens. Natural languages, conversely, evolve organically for human communication, making the precise parsing of such dependencies inherently complex and ambiguous.
Three key differences are identified:
- Structure and Semantics: Assembly languages possess well-defined structures, semantics, and conventions crucial for machine execution, enabling accurate parsing of syntactic and semantic dependencies. Natural languages lack this precise definition, making dependency parsing challenging.
- Linearity: Natural language sentences are typically linear. Assembly language, however, allows for flexible instruction ordering, including reordering instructions or moving them between basic blocks without altering overall semantics, a technique frequently deployed in compiler optimizations.
- Composition: Assembly language instructions are generally simple, consisting of a single verb and one or more operands (pronouns). Natural language sentence composition is far more intricate and varied.
These distinctions reveal why treating code as natural language can impede effective semantic learning. NLP-based methods, which typically consume sequences of tokens defined by their content and position, struggle when modifications that do not change code semantics nevertheless alter the input sequence. The talk illustrates this with three semantically equivalent variants:
- Instruction Reordering: Changing the order of independent instructions, a common compiler optimization.
- NOP Insertion: Shifting groups of instructions by inserting No-Operation (NOP) instructions, which changes token positions but not semantics.
- Register Renaming: Replacing one register with another throughout a function, which alters token content but maintains data flow semantics.
For NLP-based models, learning these semantic equivalences from diverse syntactic representations requires substantial additional network parameters and extensive training samples. This makes NLP-based methods more expensive, harder to generalize, and ultimately less efficient for binary code analysis. The authors propose that instead of forcing models to learn these inherent rules, it is more beneficial to explicitly recover and represent the well-defined semantic structures using traditional methods, and then present this richer, semantically-aware representation to deep neural networks for higher-level semantic learning.
Key Findings
▶ Watch: Fundamental differences: natural vs. assembly language (3:57)
The research presents several key findings and contributions that collectively advance the state-of-the-art in binary code similarity detection:
First and foremost, the core finding is that code is fundamentally not natural language, and attempting to apply Natural Language Processing (NLP) techniques directly to binary code for similarity detection is suboptimal. This approach overlooks critical, well-defined semantic properties of assembly language and leads to inefficiencies, particularly in challenging scenarios like cross-architecture analysis.
Second, the authors introduce the novel Semantics-Oriented Graph (SOG) representation. This is a groundbreaking contribution as it explicitly captures the deep semantic structures embedded within binary code. Crucially, the SOG is designed to discard semantically irrelevant information, such as the exact linear order of instructions (when not semantically constrained) or the specific registers used. This focused representation allows the subsequent learning models to concentrate solely on the core meaning of the code.
Third, to effectively leverage the SOG representation, the researchers developed a lightweight multi-head softmax aggregator based Graph Neural Network (GNN). This novel GNN architecture is specifically tailored to learn high-level semantics from the rich, structured information encoded in SOGs, rather than struggling with noisy, semantically ambiguous sequential inputs. The "lightweight" nature implies efficiency and better generalization.
Finally, through extensive experimentation, the work demonstrates that the proposed SOG-GNN approach achieves state-of-the-art performance across a comprehensive suite of binary function retrieval tasks. This includes superior accuracy in highly challenging cross-architecture, cross-optimization level, and cross-compiler comparisons. Furthermore, the method exhibits significantly higher accuracy in real-world vulnerability search scenarios within firmware images. A notable additional finding is that these performance gains are achieved with substantially fewer model parameters compared to existing NLP-based methods, indicating improved efficiency, reduced training complexity, and enhanced generalization capabilities.
Technical Deep Dive
▶ Watch: Examples of NLP limitations with code semantics (5:58)
The cornerstone of this research is the Semantics-Oriented Graph (SOG), a novel representation designed to explicitly capture the intrinsic semantic structures of binary code while abstracting away semantically irrelevant details. The authors argue that in assembly language, it is the semantic constraints and relations between instructions that truly matter, not their arbitrary linear order or specific positional encoding, as often emphasized in NLP. Therefore, the SOG adopts a graph representation as its fundamental structure.
The construction of an SOG systematically categorizes and integrates three distinct types of semantic structures embedded within binary code:
- Inter-instruction Relations: This category focuses on the relationships and constraints between different instructions. The SOG identifies and represents essential semantic dependencies such as execution order (control flow) and def-use relations (data flow). For instance, if the output of one instruction (definition) serves as the input for another (use), this dependency is explicitly modeled as an edge in the graph. Additionally, implicit conventions like calling conventions, which dictate how functions pass arguments and return values, are analyzed and incorporated. This initial stage forms a graph that captures the macro-level semantic interactions between instructions and basic blocks.
- Intra-instruction Structures: Moving beyond the inter-instruction level, the SOG delves into the internal structure of individual instructions. Each instruction is tokenized, and the intricate relationships within these tokens are interpreted. This includes identifying the opcode (the "verb") and its operands (the "pronouns"), as well as specific def-use relations within an instruction. For example, an instruction like
MOV EAX, [EBX+0x4]involves a definition ofEAXand uses ofEBXand the memory location it points to. These fine-grained dependencies are also added as edges, enriching the graph with micro-level semantic details.
- Elimination of Semantically Independent Information: A critical step in the SOG construction is the deliberate removal of information that, while syntactically present, is semantically irrelevant for similarity detection. The most prominent example is the specific choice of registers. For instance, whether a calculation uses
EAXorEBXmight be a compiler choice and does not fundamentally alter the data flow or computation logic if the same data is moved and processed. Therefore, the SOG eliminates these exact register references, instead focusing on the underlying data flow and the operations performed on abstract data entities. This pruning process helps the model generalize better by preventing it from overfitting to superficial syntactic variations.
The progressive construction of an SOG can be visualized as a multi-stage refinement:
- Initially, a basic graph might capture only the control flow.
- Then, inter-instruction def-use relations and calling conventions are added, forming a more robust semantic graph.
- Further, intra-instruction tokenization and their def-use relations are integrated.
- Finally, information like specific register names is abstracted away, leaving a representation that distills the complete semantic structure while discarding noise.
The resulting SOG is a rich, directed graph where nodes represent instructions, tokens, or abstract data entities, and edges represent various semantic relationships (control flow, data flow, def-use, calling conventions). This representation inherently lacks positional encoding, as the relationships, not the order, are paramount.
To effectively learn from these SOGs, the authors designed a novel lightweight multi-head softmax aggregator based GNN. While the transcript does not delve into the mathematical specifics of this GNN, its key characteristics are highlighted:
- Lightweight: Implies a more efficient architecture with fewer parameters, contributing to faster training and better generalization.
- Multi-head: Suggests the ability to process information from different "perspectives" or subspaces, potentially capturing diverse semantic features.
- Softmax Aggregator: Indicates a mechanism for combining information from neighboring nodes in the graph, likely using a weighted sum where weights are determined by a softmax function, allowing the model to focus on the most relevant neighbors for aggregation.
This specialized GNN is crucial because traditional GNNs might not be optimally suited for directly processing the highly structured and semantically abstract nature of SOGs. The custom aggregator is designed to efficiently propagate and aggregate semantic information across the SOG, allowing the network to learn robust, high-level function embeddings that accurately reflect semantic similarity regardless of syntactic variations.
Demo / Proof of Concept
▶ Watch: Introducing the Semantics-Oriented Graph (SOG) representation (7:37)
While the talk did not feature a live, interactive demonstration, the robust experimental results presented serve as a comprehensive proof of concept for the effectiveness of the Semantics-Oriented Graph (SOG) and its accompanying GNN. The evaluation focused on binary function retrieval, a task designed to identify ground truth functions (compiled from the same source code) within a large pool of binary functions, given a query function.
The experiments utilized a public dataset previously published in USENIX Security, ensuring reproducibility and comparability with prior work. This dataset is particularly challenging and diverse, encompassing binary functions generated from:
- Three different architectures: Testing cross-architecture generalization.
- Two business modes: Likely referring to different compilation flags or specific build environments.
- Five optimization levels: Ranging from no optimization to aggressive optimizations, which drastically alter binary structure.
- Eight different compiler versions: Accounting for variations introduced by different compiler toolchains.
The evaluation was meticulously broken down into four challenging subtasks to assess the method's resilience against various transformations:
- Cross-architecture retrieval: Identifying similar functions compiled for different CPU architectures.
- Cross-optimization level retrieval: Finding similar functions compiled with varying optimization settings.
- Cross-compiler and optimization level retrieval: A more complex scenario combining compiler and optimization variations.
- Cross-all variables retrieval: The most challenging task, involving variations across all architectures, optimization levels, and compiler versions.
The proposed SOG-GNN method was benchmarked against five recent state-of-the-art works in binary code similarity detection. The results were compelling: the SOG-GNN achieved the best performance across all these retrieval tasks. This indicates its superior ability to generalize and identify semantic similarities even under significant syntactic divergence caused by diverse compilation environments. A particularly noteworthy finding was that the SOG-GNN accomplished this with much fewer parameters compared to NLP-based methods. This highlights the efficiency of the SOG representation, as the model requires less capacity to learn the underlying semantics, suggesting better generalization and reduced computational overhead.
Beyond retrieval tasks, the research also demonstrated the practical utility of the SOG-GNN in a real-world vulnerability search scenario. The method was tested on 12 firmware images from three different vendors. In this context, the goal was to identify known vulnerable functions within these closed-source firmware binaries. The SOG-GNN achieved much higher accuracy compared to related works, both for searching identical functions and for detecting variants of vulnerable functions that might have undergone compilation changes. This showcases the immediate applicability of the SOG-GNN for enhancing vulnerability discovery and patch management in complex, real-world systems.
Defensive Implications
▶ Watch: Key principles of SOG: semantic constraints over position (8:00)
The advancements presented by the Semantics-Oriented Graph (SOG) and its specialized GNN have profound implications for defensive security strategies, offering more robust and efficient tools for protecting systems against emerging threats.
First and foremost, the enhanced accuracy and generalization capabilities of this method significantly improve vulnerability discovery and patching. Defenders can leverage the SOG-GNN for more reliable and efficient searching of known vulnerable functions (e.g., those associated with specific CVEs) within closed-source firmware or proprietary binaries. This is critical for identifying whether a vulnerability patched in one version of a product still exists in other compiled variants or across different architectures, enabling proactive risk assessment and more targeted patch deployment.
Secondly, the method strengthens software supply chain security. By accurately detecting binary code similarity, organizations can identify instances of unauthorized code reuse, intellectual property theft, or license violations within third-party components. This capability helps ensure the integrity and compliance of software components, reducing the risk of hidden vulnerabilities or legal liabilities stemming from code dependencies.
Thirdly, in the realm of malware analysis and threat intelligence, the SOG-GNN offers a powerful tool for identifying variants of known malware families. Malware authors frequently employ obfuscation techniques, different compilers, or optimization levels to evade detection. The SOG-GNN's ability to maintain semantic understanding despite such syntactic variations makes it highly effective in clustering malware samples, accelerating the development of new threat signatures, and understanding the evolution of attack campaigns.
Furthermore, the method's efficiency, characterized by fewer model parameters, translates into practical benefits for defenders. It implies potentially faster training times, reduced computational resources for inference, and better scalability for analyzing vast repositories of binary code. This efficiency is crucial for large-scale security operations, enabling more frequent and comprehensive scans of software assets.
Finally, by explicitly focusing on core semantic structures and discarding irrelevant syntactic noise, the SOG-GNN promises to reduce false positives and false negatives in binary similarity detection. This leads to more trustworthy security assessments, allowing security teams to allocate their resources more effectively to genuine threats rather than chasing spurious alerts. The ability to accurately identify semantic equivalence across diverse compilation scenarios provides a more reliable foundation for automated security analysis, code auditing, and incident response.
Key Takeaways
- Binary code is not natural language: Treating binary code as natural language for similarity detection is inefficient and inaccurate, overlooking crucial code-specific semantic properties and leading to poor generalization, especially in cross-architecture scenarios.
- Semantics-Oriented Graph (SOG) representation: The novel SOG explicitly captures the well-defined semantic structures of binary code, including inter-instruction relations (control flow, data flow, calling conventions) and intra-instruction structures, while discarding semantically irrelevant information like specific register choices or arbitrary instruction order.
- State-of-the-art performance: The SOG, combined with a lightweight multi-head softmax aggregator based GNN, significantly outperforms five recent state-of-the-art methods across challenging binary function retrieval tasks, including cross-architecture, cross-optimization, and cross-compiler comparisons.
- Enhanced vulnerability search: The proposed method demonstrates substantially higher accuracy in real-world vulnerability search within 12 firmware images from three vendors, effectively identifying known vulnerabilities even when functions are compiled differently.
- Efficiency and generalization: The SOG-GNN achieves superior performance with significantly fewer model parameters than NLP-based methods, indicating improved efficiency, reduced computational cost, and better generalization capabilities across diverse compilation environments.
- Foundational for defensive security: This research provides a more robust and reliable foundation for critical security tasks such as vulnerability discovery, patch analysis, malware variant detection, and ensuring software supply chain integrity.
About the Speaker(s)
The talk was presented by a colleague on behalf of Haojie He, who is credited as the first author. The research is a collaborative effort involving multiple contributors from Shanghai Jiao Tong University, ANT Group, and the University of Texas at Arlington. The team includes Haojie He, Xingwei Lin, Ziang Weng, Ruijie Zhao, Shuitao Gan, Libo Chen, Yuede Ji, Jiashui Wang, and Zhi Xue. Their collective expertise spans binary analysis, deep learning, and security research, contributing to this significant advancement in binary code similarity detection.
Reviews
Dr. Zero (Offensive Security Researcher) — MUST SEE
This research brutally dismantles the lazy assumption that binary code can be treated as natural language, a critical and necessary correction. The novel Semantics-Oriented Graph (SOG) representation, coupled with a lightweight GNN, offers a genuinely new and efficient paradigm for binary similarity detection. It delivers state-of-the-art results across architectures and optimizations, fundamentally improving vulnerability discovery and malware analysis.
Heather Calloway (CISO) — STRONG ACCEPT
This research provides a critical correction to how we approach binary code analysis, moving past inefficient NLP models to a more semantically aware graph representation. Its state-of-the-art performance in vulnerability discovery, supply chain integrity, and malware detection offers significant, actionable improvements for security operations and risk management. This changes how our technical teams should build and deploy analysis tools.