A Taxonomy of C Decompiler Fidelity Issues
Luke Dramko (PhD student · Carnegie Mellon University), Jeremy Lacomis, Edward J. Schwartz, Bogdan Vasilescu, Claire Le Goues
33rd USENIX Security Symposium · Day 1 · USENIX Security '24 · USENIX Security '24
Overview
This talk, presented by Luke Dramko from Carnegie Mellon University, delves into the inherent limitations and discrepancies found in the output of modern decompilers. Decompilers are indispensable tools in binary analysis, converting executable code back into a higher-level representation, typically C. This process is crucial for tasks like malware analysis, vulnerability research, and even patching legacy software when original source code is unavailable. However, the decompiled output often lacks the clarity and readability of the original source, making analysis challenging.
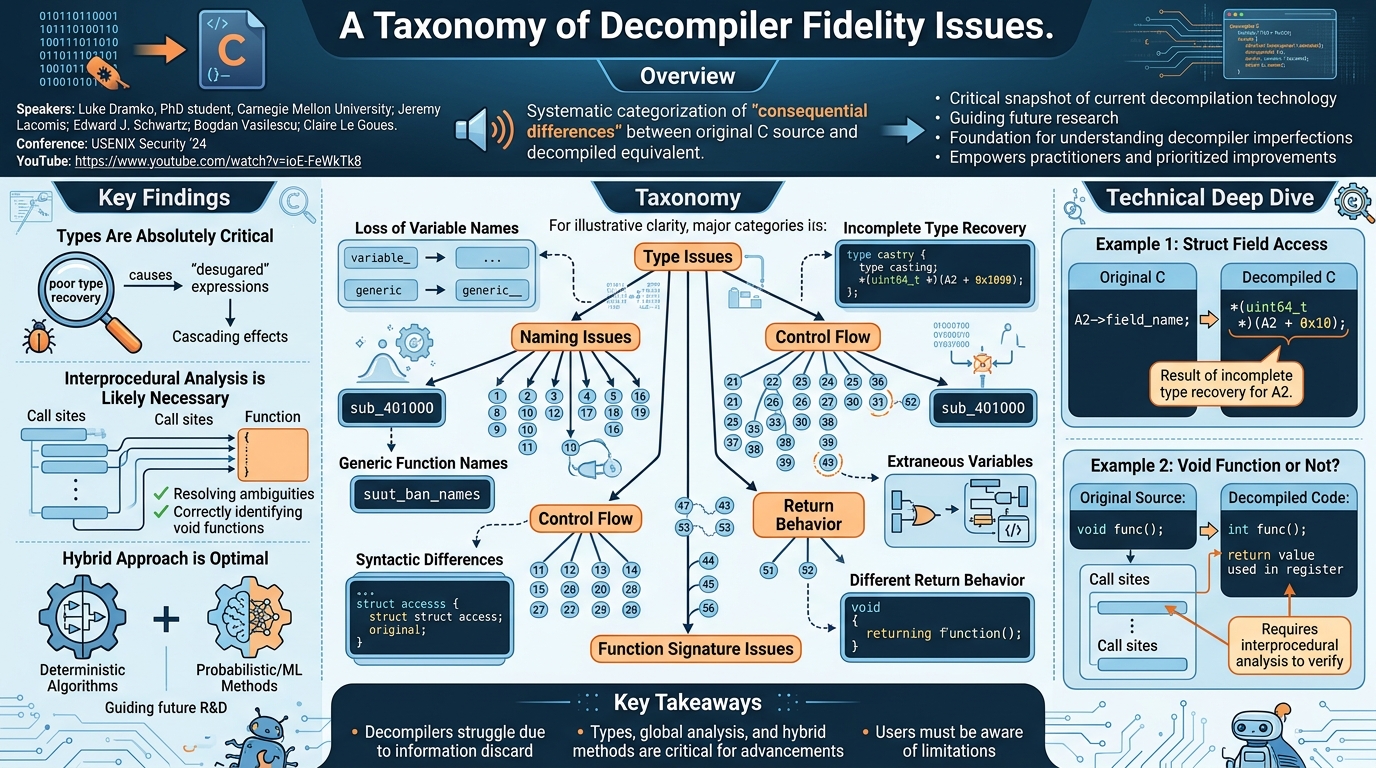
Key moments
- 0:00 Introduction to decompilers and fidelity issues
- 2:15 Methodology: open coding and code alignment
- 4:00 Examples of decompilation fidelity issues
- 5:00 Key Takeaway 1: Type recovery is critical
- 6:00 Key Takeaway 2: Interprocedural analysis needed
- 7:00 Key Takeaway 3: Interprocedural type recovery
A Taxonomy of C Decompiler Fidelity Issues
Speakers: Luke Dramko, PhD student, Carnegie Mellon University; Jeremy Lacomis; Edward J. Schwartz; Bogdan Vasilescu; Claire Le Goues
Conference: USENIX Security '24
YouTube: https://www.youtube.com/watch?v=ioE-FeWkTk8
Overview
This talk, presented by Luke Dramko from Carnegie Mellon University, delves into the inherent limitations and discrepancies found in the output of modern decompilers. Decompilers are indispensable tools in binary analysis, converting executable code back into a higher-level representation, typically C. This process is crucial for tasks like malware analysis, vulnerability research, and even patching legacy software when original source code is unavailable. However, the decompiled output often lacks the clarity and readability of the original source, making analysis challenging.
The core of Dramko's research is the development of a comprehensive taxonomy that systematically categorizes the "consequential differences" between original C source code and its decompiled equivalent. By meticulously identifying and classifying 52 distinct types of fidelity issues, the research provides a critical snapshot of the current state of decompilation technology. This systematic approach aims not only to highlight existing shortcomings but also to guide future research and development efforts, ultimately paving the way for more accurate and human-readable decompiled code.
The significance of this work lies in its foundational contribution to the field of reverse engineering. By providing a structured understanding of decompiler imperfections, the taxonomy empowers practitioners to better interpret decompiled output and helps decompiler developers prioritize improvements. This, in turn, enhances the efficiency and accuracy of security analyses that rely heavily on the ability to understand compiled binaries without access to their original source.
Background
▶ Watch: Introduction to decompilers and fidelity issues (0:00)
The journey from high-level source code to executable binary is a process of optimization and abstraction removal. Compilers, designed for machine execution efficiency, discard vast amounts of information that are primarily present for programmer readability and maintainability. This includes crucial elements like meaningful variable names, detailed type information, and often even original function names (unless required for dynamic linking). When a decompiler attempts to reverse this process, it faces an inherently lossy problem. Without the discarded source-level context, the decompiler must make informed guesses, leading to a significant divergence between the original and the reconstructed code.
Despite considerable advancements in decompilation technology over the years, the resulting code remains a far cry from its source counterpart. For instance, generic placeholders replace expressive variable names, and incomplete type recovery often results in complex, "desugared" expressions instead of concise high-level constructs. This gap between ideal and actual decompilation fidelity hinders effective analysis, forcing security researchers and reverse engineers to spend additional time deciphering and reconstructing the original intent.
The problem, as highlighted by Dramko, is not merely the existence of these differences, but the lack of a systematic and comprehensive understanding of their nature and impact. Prior work in decompilation has focused on specific algorithms or improvements, but a holistic categorization of all consequential differences was missing. This research addresses that gap by providing a rigorous framework to identify, classify, and analyze these fidelity issues, thereby laying the groundwork for more targeted and impactful future decompiler advancements. The aim is to move beyond anecdotal observations of decompiler shortcomings towards a structured, empirical understanding that can drive the next generation of decompiler development.
Key Findings
▶ Watch: Examples of decompilation fidelity issues (4:00)
The central contribution of this research is the development of a comprehensive taxonomy of decompiler fidelity issues, comprising 52 distinct entries arranged hierarchically. This taxonomy was constructed using open coding, a qualitative empirical research method applied to pairs of original source and decompiled C functions. The researchers defined "differences" with respect to an ideal, perfectly faithful decompilation that would be identical to the original source. A novel abstraction called an alignment was introduced, where aligned code fragments are those that fulfill the same role within a function, even if their syntactic forms differ.
Analyzing this extensive taxonomy revealed several critical insights for the future of decompilation:
- Types are Absolutely Critical: A significant number of observed fidelity issues were identified as downstream effects of a decompiler's inability to accurately reconstruct variable types. Poor type recovery leads to "desugared" expressions, obscures data structures, and generally degrades the readability and accuracy of the decompiled output. This finding underscores the paramount importance of improving type inference mechanisms in decompilers.
- Interprocedural Analysis is Likely Necessary: Many ambiguities and inaccuracies in decompiled code cannot be resolved by analyzing a single function in isolation. For instance, determining if a function is truly
voidor if a register's value is an intended return value often requires examining all its call sites across the program. Similarly, recovering complex data structures, especially recursively defined ones, necessitates analyzing their usage patterns across multiple functions (e.g., allocation, initialization, and various field accesses).
- A Hybrid Approach Combining Deterministic and Probabilistic Methods is Optimal: The research suggests that both deterministic and probabilistic (e.g., machine learning-based) methods have distinct yet complementary roles in advancing decompilation. Deterministic algorithms excel at providing a solid foundation and can offer correctness guarantees. However, they struggle to recover information explicitly discarded by the compiler, such as meaningful names. Probabilistic methods, on the other hand, are well-suited for inferring such lost information, like predicting specific variable names or distinguishing between semantically similar but structurally different constructs (e.g., a struct field access vs. an array element access). The combination leverages the strengths of both approaches.
These findings collectively highlight that future decompiler development must move beyond local, single-function analysis and incorporate sophisticated global analysis techniques, with a strong emphasis on robust type recovery, and embrace hybrid algorithmic strategies to achieve significant breakthroughs in fidelity.
Technical Deep Dive
▶ Watch: Key Takeaway 1: Type recovery is critical (5:00)
The core of the research is the detailed categorization of decompiler fidelity issues. The taxonomy, with its 52 hierarchical entries, captures a wide spectrum of discrepancies. Dramko illustrated several key examples of how decompiled code diverges from its original source:
- Loss of Variable Names: During compilation, high-level variable names (e.g.,
user_input_buffer) are discarded as they hold no functional relevance for execution. Decompilers are forced to replace these with generic placeholders likeA1,v2, orvar_8h, significantly reducing code readability and hindering human understanding of the program's logic. - Incomplete Type Recovery: Similar to names, much of the precise type information (e.g.,
struct UserData *,char[]) is lost. Decompilers often struggle to fully reconstruct these types, leading to generic types (e.g.,uint64_t) or complex casting sequences where a simple struct field access would suffice. - Generic Function Names: Unless a function is part of a dynamically linked library where its name is preserved for symbol resolution, internal function names are often discarded or mangled. Decompilers then assign generic names like
sub_401000, making it harder to infer the function's purpose without manual analysis. - Extraneous Variables: Decompiled code can sometimes introduce variables that have no direct equivalent in the original source. These might be artifacts of compiler optimizations, register usage, or intermediate values created during the decompilation process, adding noise and complexity.
- Syntactic Differences for Semantically Equivalent Operations: A prime example of this is the representation of struct field access. In source code, one might write
A2->field_name. However, without complete type information forA2and the struct definition, a decompiler often renders this as a series of operations like(uint64_t )(A2 + 0x10). This "desugared" form, while semantically identical (accessing a 64-bit value at an offset of 0x10 fromA2), is syntactically verbose and much harder to parse for a human analyst. - Different Return Behavior: A compiler might optimize a
voidfunction by using the return register for general-purpose operations. When decompiled, the decompiler, unsure if the value in the return register is coincidental or intended, often conservatively assumes a return value, leading to a function that appears to return a value when the original wasvoid.
The profound impact of type recovery was a recurring theme. The (uint64_t )(A2 + 0x10) example directly illustrates how the lack of a proper struct type for A2 forces the decompiler to generate a low-level, desugared representation instead of a high-level struct field access. This single issue cascades, making the code harder to read and analyze, and obscuring the underlying data structures.
To address these limitations, the talk emphasized the necessity of interprocedural analysis:
- Void Function Detection: To correctly identify if a function is
void, a decompiler cannot rely solely on the function's assembly. It must analyze all call sites within the program. If none of these call sites utilize the return value of the function, it strongly suggests the function was originallyvoid. - Complex Type Recovery (e.g., Structs, Recursive Data Structures): Recovering the type of a variable like
A2might involve multiple pieces of evidence. ObservingA2 + 0x10andA2 + 0x24suggestsA2is a struct. Furthermore, if the values at these offsets are passed to recursive calls of the same function, it strongly hints thatA2is a recursively defined data structure, such as a binary tree, where0x10and0x24might be offsets to its child nodes. However, fully recovering the entire struct definition, including other fields not used in the current function, would require analyzing an "arbitrary number of other functions" whereA2is allocated, initialized, or used, providing the necessary contextual clues.
Finally, Dramko discussed the role of deterministic vs. probabilistic methods. Deterministic algorithms, based on program analysis, provide a reliable starting point, identifying patterns like A2 + offset. However, distinguishing between a struct field access and an array element access (e.g., array[2] vs. struct->field) when the offset is a fixed non-zero value, or inferring meaningful names, often requires probabilistic methods, potentially leveraging machine learning. For instance, while A2 + 0x10 could be an array access, in practice, a fixed non-zero offset often indicates a struct field, a pattern that probabilistic models can learn and predict. Similarly, generating human-readable names for variables, structs, and fields, which are entirely discarded by the compiler, is inherently a task for probabilistic inference. This hybrid approach, combining the rigor of deterministic analysis with the inference capabilities of probabilistic models, is presented as the most promising path forward for significant decompiler advancements.
Demo / Proof of Concept
▶ Watch: Key Takeaway 2: Interprocedural analysis needed (6:00)
The talk primarily focused on presenting the methodology behind building the taxonomy and its resulting insights, rather than demonstrating a new decompiler or exploit. The "demonstration" was conveyed through illustrative code examples presented on slides, showcasing specific fidelity issues (like generic variable names, desugared struct accesses, and incorrect return types) and explaining how the developed taxonomy would classify these differences. The purpose was to provide concrete instances of the problems identified, rather than a live execution of a software tool.
Defensive Implications
▶ Watch: Key Takeaway 3: Interprocedural type recovery (7:00)
While this research focuses on improving the tools used for analysis rather than direct defensive measures, its implications for security defenders are significant and multifaceted.
Firstly, the taxonomy serves as a crucial educational resource for anyone relying on decompilers for malware analysis, vulnerability research, or reverse engineering legacy software. Defenders must understand the inherent limitations of current decompilation technology. Blindly trusting decompiled code can lead to misinterpretations, missed vulnerabilities, or incorrect conclusions about malware behavior. Awareness of issues like generic variable names, incomplete type recovery, and potentially incorrect function signatures (e.g., a void function appearing to return a value) is paramount. This knowledge encourages a more critical approach, prompting analysts to cross-reference decompiled output with raw assembly code, especially for critical sections.
Secondly, the findings highlight areas where manual effort is often required. When decompiled code is unclear, a defender might need to manually reconstruct data structures, infer variable types, or trace interprocedural data flow, precisely because the decompiler could not. The taxonomy helps to categorize why this manual effort is needed, making the process more systematic. For instance, knowing that type recovery is a major weakness means a defender should prioritize manual type inference when analyzing complex data structures.
Thirdly, for organizations developing or customizing their own reverse engineering toolchains, this research provides a roadmap for decompiler improvement. By identifying the most impactful fidelity issues (e.g., type recovery, interprocedural analysis), decompiler developers can prioritize features that will yield the greatest benefit for security analysts. As decompilers become more accurate and produce higher-fidelity code, the time and effort required for binary analysis will decrease, allowing defenders to analyze more threats or discover vulnerabilities faster.
Finally, the discussion on deterministic and probabilistic methods suggests that future advanced decompilers might integrate machine learning. Defenders should be aware that while this promises better results (e.g., meaningful names), it also introduces a potential for probabilistic errors or "hallucinations" if the models are not robust. Therefore, a degree of skepticism and verification will always remain essential, even with highly advanced decompilers. In essence, this research equips defenders with a deeper understanding of their primary analysis tool, enabling them to use it more effectively and intelligently.
Key Takeaways
- Decompilers face significant challenges in faithfully reconstructing original source code due to information discarded during compilation (e.g., names, types).
- A comprehensive taxonomy of 52 hierarchical fidelity issues systematically categorizes the consequential differences between original and decompiled C code.
- Type recovery is identified as absolutely critical; its absence cascades into numerous other issues, leading to "desugared" and less readable code.
- Interprocedural analysis is often essential for resolving ambiguities and accurately reconstructing complex data structures and function behaviors (e.g., distinguishing void functions).
- Advancements in decompilation will likely require a hybrid approach, combining deterministic algorithms for correctness with probabilistic (e.g., machine learning) methods for inferring discarded information like meaningful variable names.
- Users of decompilers must be acutely aware of these inherent limitations and not blindly trust decompiled output, often requiring cross-referencing with assembly and manual analysis for critical insights.
About the Speaker(s)
The primary speaker, Luke Dramko, is a PhD student at Carnegie Mellon University. He presented this research, highlighting his work in understanding and categorizing the challenges in decompiler fidelity. His co-authors on this paper include Jeremy Lacomis, Edward J. Schwartz, Bogdan Vasilescu, and Claire Le Goues, all affiliated with Carnegie Mellon University, contributing their expertise to this comprehensive study on decompilation.
Reviews
Dr. Zero (Offensive Security Researcher) — MUST SEE
This research delivers a critical, systematic taxonomy of 52 decompiler fidelity issues, providing a foundational understanding of the inherent limitations in converting binaries back to C. It’s essential for anyone who relies on decompilers, offering actionable insights into common discrepancies and a clear roadmap for future tool development, especially concerning type recovery and interprocedural analysis.
Heather Calloway (CISO) — STRONG ACCEPT
This research provides a precise, unsentimental assessment of a critical security tool's limitations. By systematically categorizing how decompiled code diverges from its source, it offers foundational clarity for security operations teams, enabling more accurate malware analysis and vulnerability research, directly influencing our ability to manage business risk.